Injecting small VLMs with strategies for tool-use on videos
Aditya Chinchure, PhD student, CV & NLP at UBC.
- Notebook
- Current Work
- Status
- Building
- Noted
- 2026-10-21
- Length
- 205 words
- Read
- 1 min
Small VLMs are quite capable at tool use. I am working on a problem where we want to use tool-use agentic VLMs to study videos generated by T2V models, and identify errors in them. I provide the model with tools for viewing frames from videos at higher fps, showing frames side-by-side for comparisons, zooming into different frame regions, and even optical flow based frame motion comparison.
Here’s something interesting I found: models like Qwen 3.5 VL 9B are absolutely capable of tool-use, but they are hampered by their inability to reason about the problem well, come up with hypotheses to test, and strategically use tools.
Research Question
If a bigger model, say Opus 5.5 or GPT-6 Sol, could provide the Qwen model with a strategy, can this strategy be injected into Qwen’s multi-turn conversation to improve tool use?
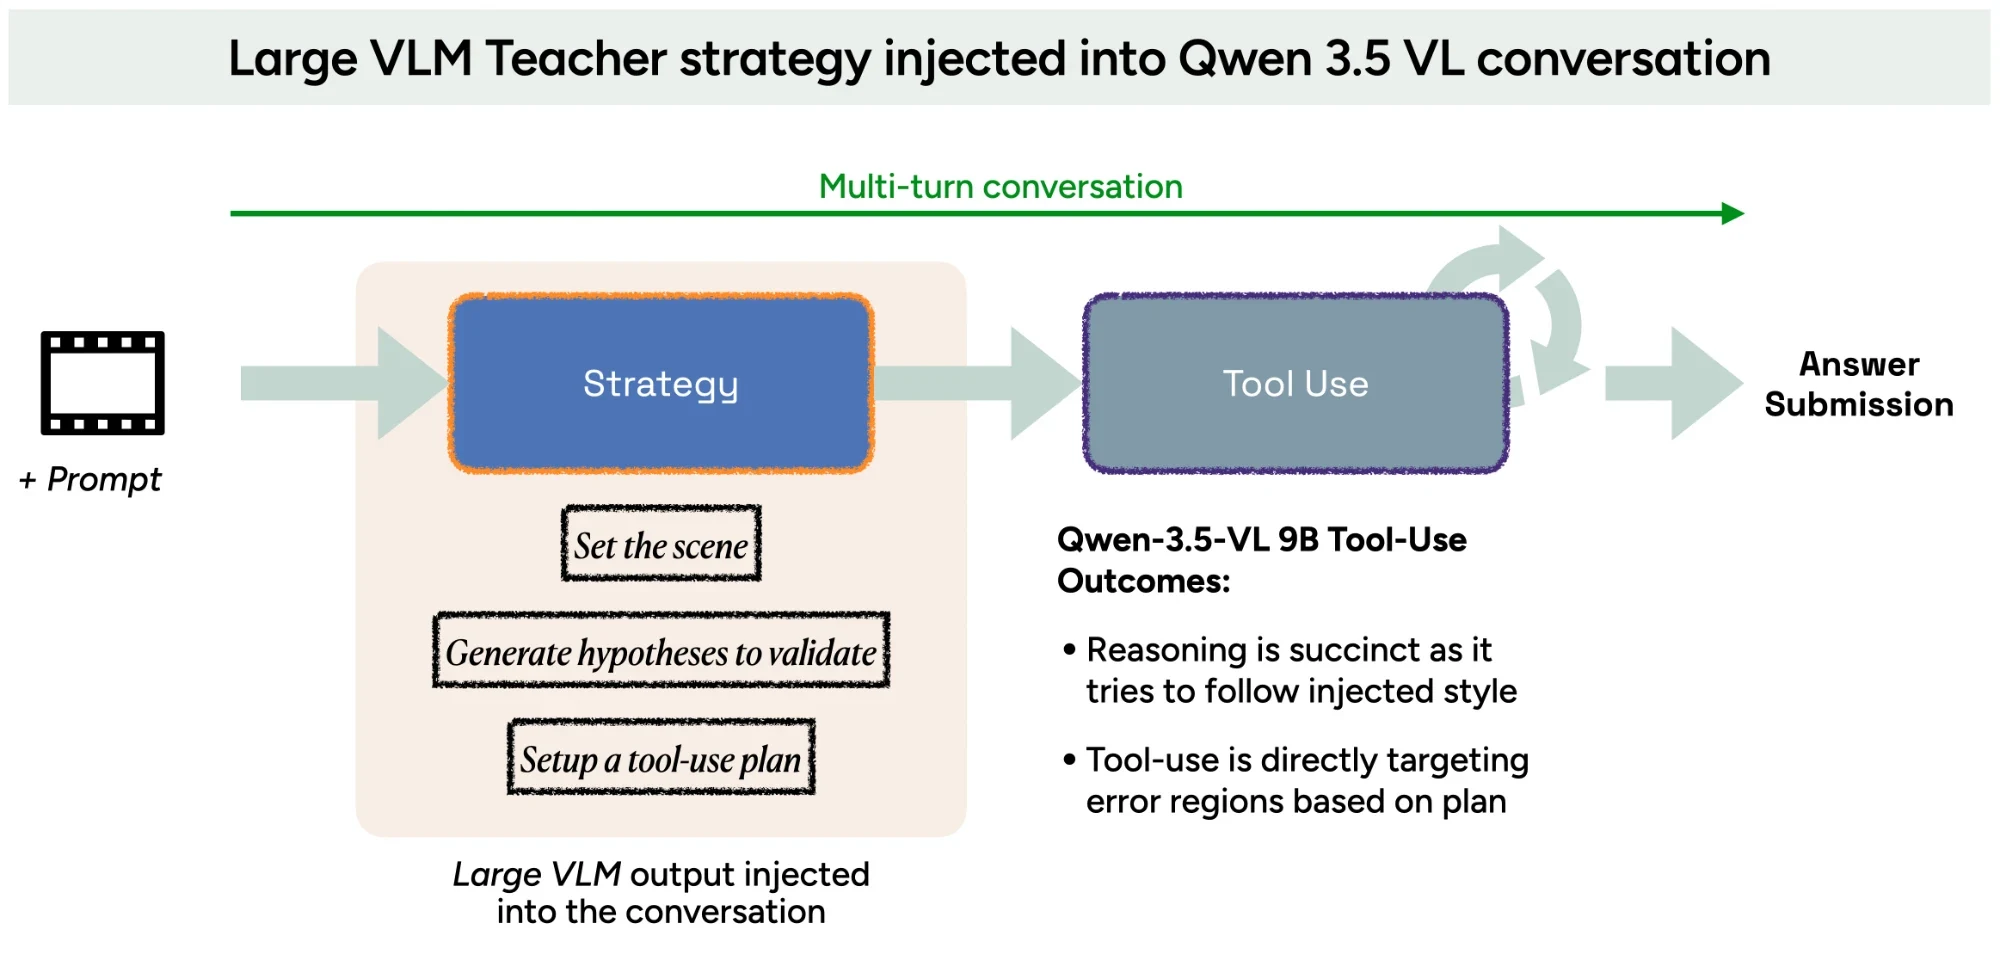
The short answer is YES! In fact, it produced some rather interesting outcomes… not only did Qwen become more accurate at tool-use, but its reasoning traces on the video were shorter, more succinct and more confident. This side effect is interesting: by modifying the expectation of how the Qwen model should think about the video, it started adapting that thinking setting to all future turns.